Unstable Unicorns advisor
A rules engine, a search-plus-network AI and phone and browser apps for playing the card game Unstable Unicorns against a machine.
I've played Unstable Unicorns myself, and it's one of a few card games I've played where I could see a computer being a decent opponent. I was also curious whether a program could beat my friends, my family, or me. So I built one for the real, physical deck. It isn't affiliated with the publisher, and it doesn't use their card art or card text.
The game is about building a stable of unicorns while everyone else tries to wreck it. Hands are hidden, and any card you play can be cancelled by a Neigh card, which can itself be cancelled by another Neigh.
First I had to teach a computer the rules, all 127 cards of them. Then I needed it to choose moves. It does that with a neural network, which has learned what a good position looks like, plus some thinking ahead. Before it moves, it imagines hundreds of ways the game could continue (more on the harder levels) and picks the move that did best, like a chess player, except it has to guess which cards you're holding because it can't see your hand. It started by copying simple scripted opponents I'd written, then learned by playing against them and against itself over and over.
There are a few ways to play it. The first is with the real deck: I tell a phone app what happens at the table, and it tells me what to do for the AI, so my hand stays secret. There's also a browser version with four difficulty levels, where the harder levels just think longer, and a version for three players.
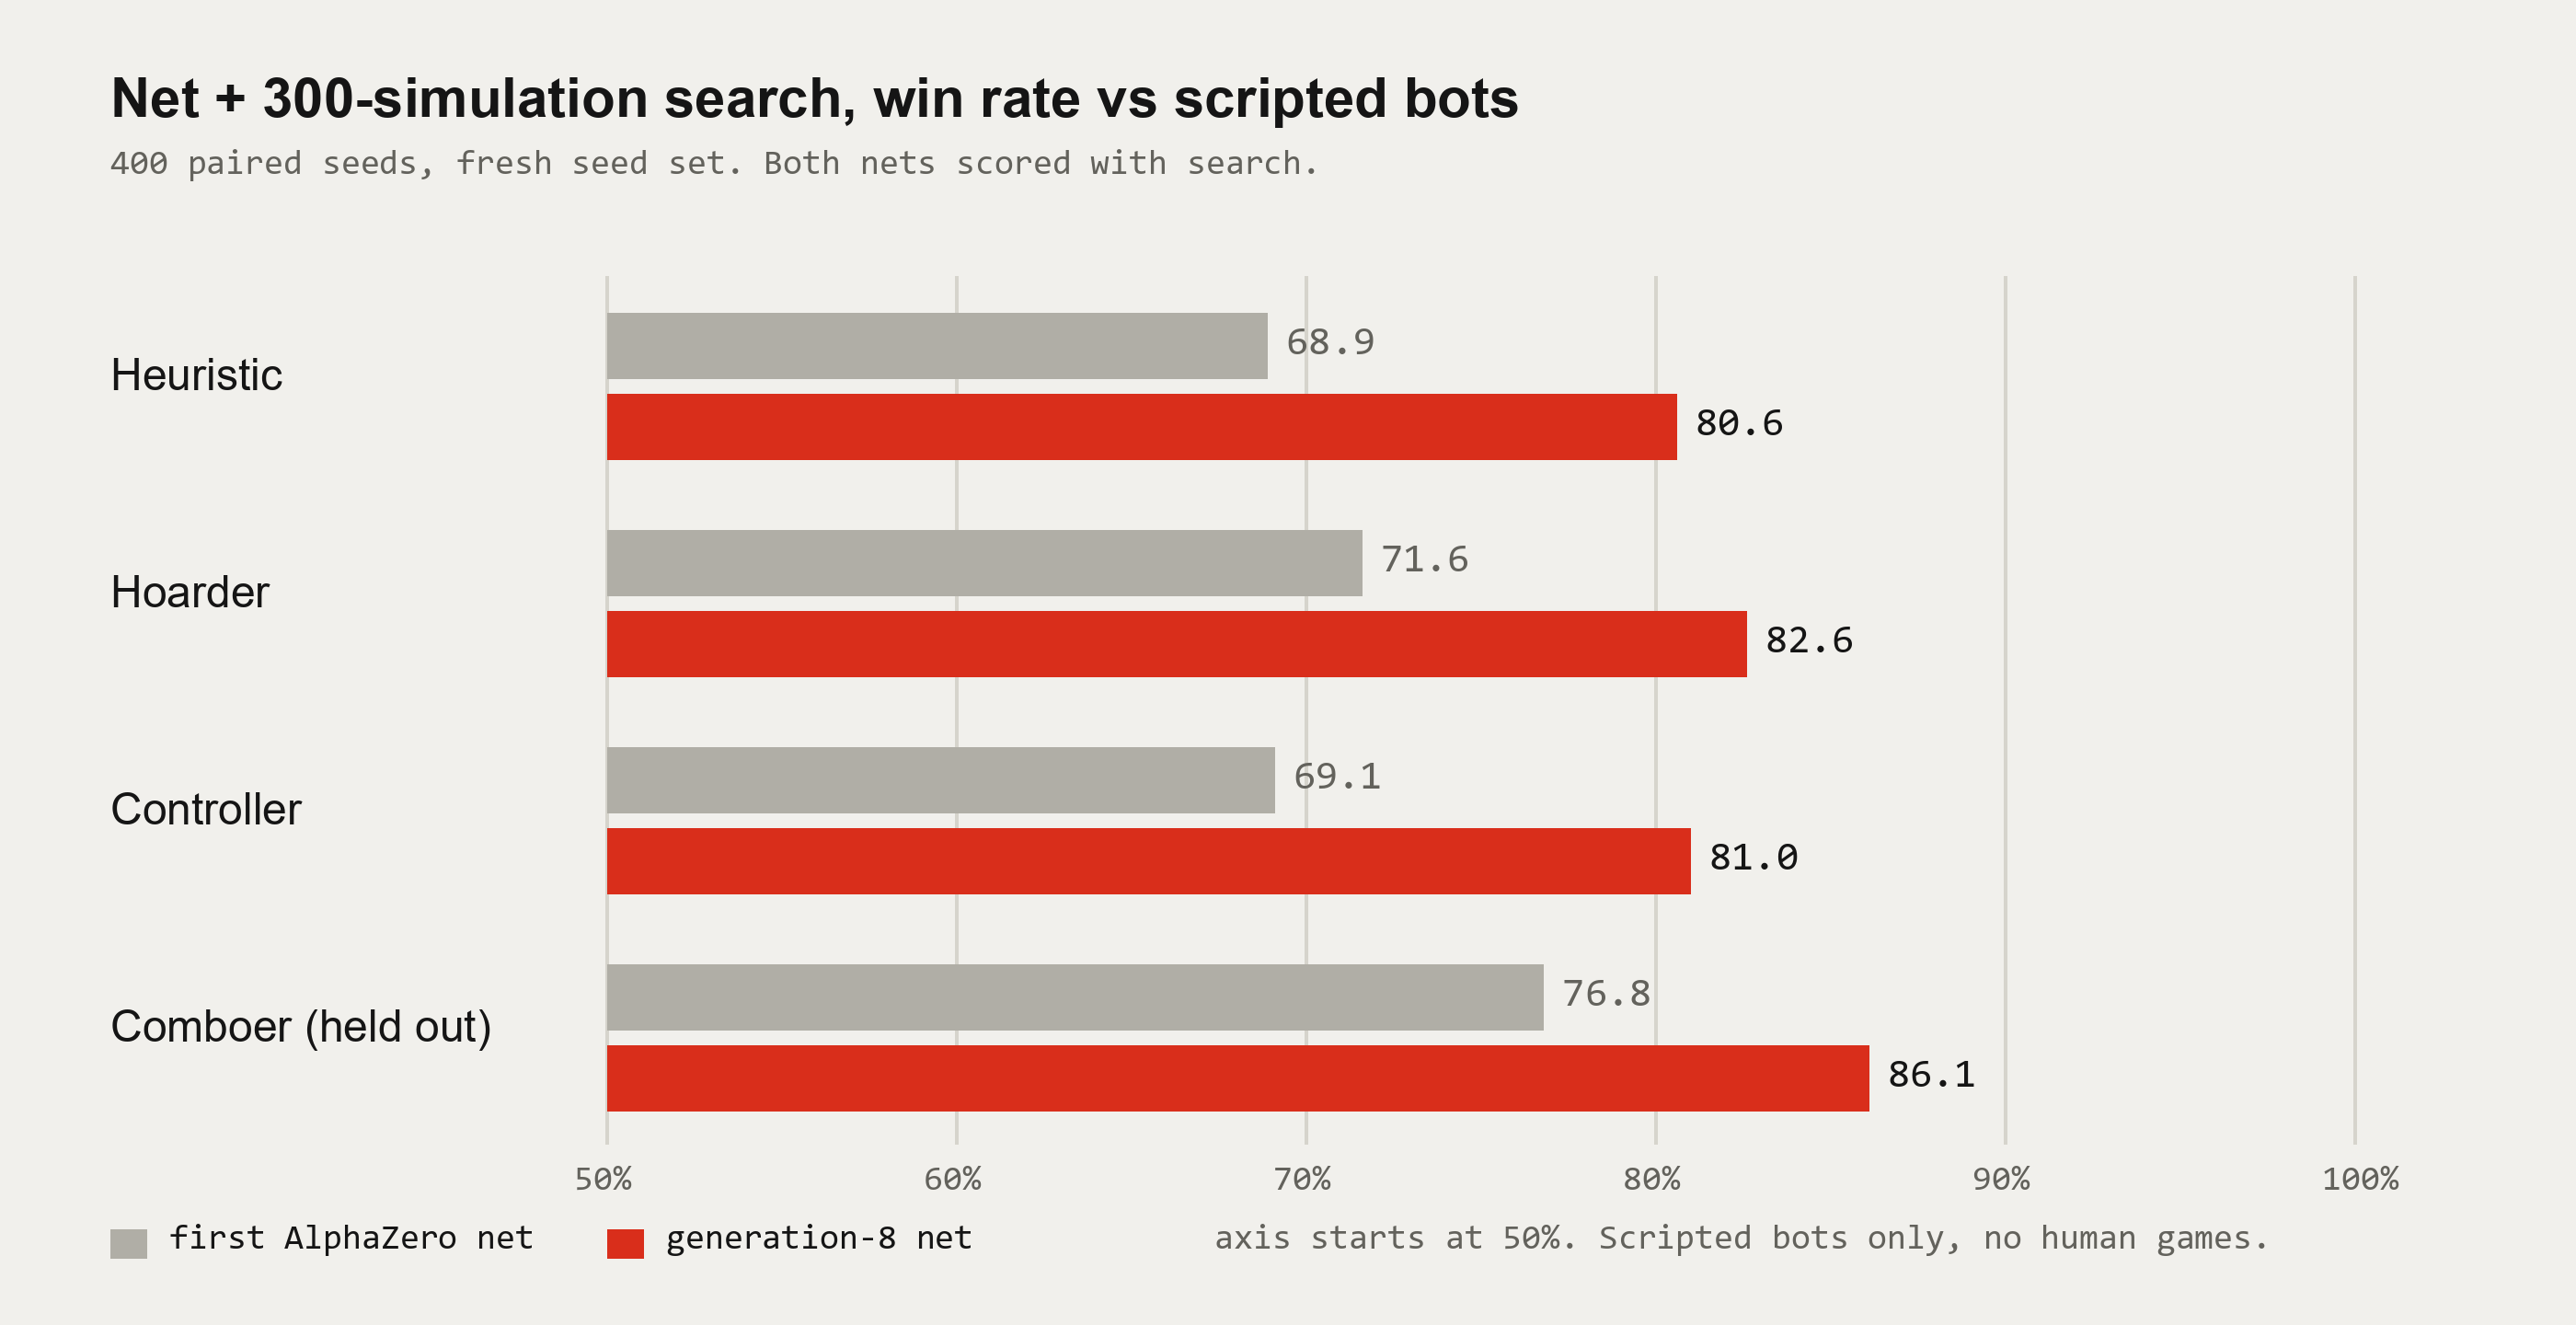
How good is it? Against the simple scripted opponents, the latest version wins about 8 games out of 10, about 10 more wins in 100 than the version before it. In the three-player game it wins about half against two scripted opponents, where chance would give it a third. Those opponents aren't strong players, though, and I haven't measured the AI against people, so I can't say how it does against a good one.
The thing I didn't expect, from watching the games the AI plays, is how big an advantage it is to start first. I had no idea before. It's a lot bigger than I would have guessed.
Plenty didn't work. A long string of tweaks to the network changed nothing, and for a while I thought a better training method had failed, when really I was judging it the wrong way: my test made good versions look bad. I also built a much faster copy of the game that runs on a graphics card, to train on, but it didn't follow the rules closely enough, and training on it made the AI worse at the real game.
What's next
The thing I haven't done is the one that matters most: play it against real people and find out how strong it really is. That means my friends and family first, and then me, which is the match I'm most curious about.
What I wanted
I've played Unstable Unicorns myself, and it's one of the few card games I've played where I could see a computer taking a seat at the table. I was also curious whether a program could beat my friends, my family, or me. Mechanically it's a commercial card game with hidden hands and a reaction mechanic: any card you play can be cancelled by a Neigh, which can itself be Neighed. I wanted an opponent for the real, physical deck, and later an advisor for three-player tables. It isn't affiliated with the publisher and doesn't use their card art.
I wrote it twice. The first version, from April, got lost, and what's here is the July 2026 rewrite. I started from the official second edition rules and wrote the tests from those, not from whatever the engine happened to do. There are a few hundred of them, plus a fuzzer that plays thousands of random games and checks that no card ever appears or vanishes.
How it works
The engine is plain Python with the full 127-card deck. The decision everything else hangs on is that every choice is a decision node. Picking a target, discarding, answering a Neigh window: the engine never calls back to ask, it just reaches a state where some seat has to act. So the search, the network, a scripted bot and a person all use the same two calls, legal_actions and step, and a seat only ever sees observation(seat), with the hidden cards masked.
The player is a residual network (about 8 million parameters, six blocks of width 768, 1,056 input features, a policy over 97 action slots and a value head) wrapped in determinized information-set MCTS. Search can't see your hand, so before each simulation it deals the cards it can't see at random, consistent with everything that's public, and then searches that world.
What is determinized search?
Ordinary tree search assumes it can see the whole game, which in a card game means it plans against the cards you are really holding. That is cheating. Determinization fixes it: before each simulation the search deals out the unseen cards at random, consistent with what it has actually seen, and treats that guess as the true state. After many simulations with different guesses, the moves that hold up across most of them score best. It never peeks. The known weakness is that it can't value hiding information or bluffing, because inside each guess everything is already known.
In both two-player apps every AI move goes through search. In the three-player digital game the AI drops to raw network moves once a turn's time budget is spent, so a click never hangs. In the two-player digital game the four difficulty levels are just search budgets, from 150 simulations up to 1,600. The three-player levels run 25 to 220.
The table companion is the one for a real deck. The AI is seat 0 and you are its hands. The app always shows exactly one prompt, either "do this for the AI" or "what happened?", and asks only for what's visibly done, never for your hand. The engine normally skips a Neigh window when it can prove the other side has no Neigh. That proof is wrong when the other hand is hidden, so the live version opens the window whenever your unseen cards could include one. Random pulls work the same way: the engine's pick is only a guess, and you confirm the card that was really pulled. A misclick can be undone, repeatedly, from a stack of snapshots, and the win-probability bar is the value head's opinion of the AI's chances.
Here is the Neigh pile on its own. Every response lands on top of the pile, only the top card can be answered, and when everyone has passed the pile resolves from the top down. You can try it below. It's a toy, and it leaves out Super Neigh, which can't be Neighed, and Yay, which makes everything its owner plays safe from Neighs.
Results
Training started by imitating scripted bots, then moved to league self-play against scripted styles (heuristic, hoarder, controller, rusher, disruptor, with a comboer kept out of training for testing). The raw network plateaued at roughly 55% against the heuristic bot, and search added about 12 to 15 points on top. After that I ran an AlphaZero-style loop on a rented cloud box, about 50 cents of rented time for the first run and about a dollar fifty for the second.
What does AlphaZero-style training mean here?
The network plays games against itself, with search choosing the moves. Search is stronger than the network alone, so the moves it picks are better training targets than the network's own guesses. The network learns to predict the search's choices and who won, which makes the next round of search stronger, and so on. The risk is that it only learns to beat itself, so each new network has to prove it beats the previous one before it gets promoted. That promotion test is the gate in the diagram.
| Opponent | Before | After |
|---|---|---|
| Heuristic | 68.9% | 80.6% |
| Hoarder | 71.6% | 82.6% |
| Controller | 69.1% | 81.0% |
| Comboer (held out of training) | 76.8% | 86.1% |
The comboer never appeared in training, and it moved by about 9 points, so the gain isn't the net getting used to the opponents it trained against.
The three-player version has its own network (1,342 inputs, 98 actions, about 8.6 million parameters) and maxn search. It started from imitating the heuristic bot, then self-played for 80 generations of 2,500 games each, roughly 200,000 games in one overnight run for about $3 of rented time. Each result below is 90 games with 120 simulations of search and the seats rotated, so it carries about plus or minus 10 points. Chance in a three-way game is 33%.
How does search work with three players?
Two-player search can score a position with one number, because what's good for me is bad for you. With three players that breaks, since a move can be good for one opponent and bad for the other. In maxn every position carries one score per player, and whoever is to move picks the option that's best for their own score. Nothing about teaming up is written in. Going after the leader falls out of each player looking after itself.
With search off the three-player network was weak, about 27% against the heuristic bots at generation 30 (a small sample), against 46% with search on in the larger test. Search lifted it a lot, as it did in the two-player game. Against two bots deliberately ganging up on it, the final net held about a fair share, 31%, rather than being crushed to nothing. It didn't beat the coalition.
What didn't work
Roughly a dozen tweaks to the raw network either changed nothing or made it worse: gentle fine-tunes, bigger runs of self-play, distilling a search into the net, training from scratch, and a small AlphaZero pilot that fell to 31%. Some of those results may have been the same measuring mistake described next.
The first real AlphaZero run stopped at generation 3, on a kill rule I'd set in advance: three gate scores in a row below 50%. They were 0.371, 0.349 and 0.393. The gate was wrong, not the net. It scored the raw policy sampled at temperature 1, and a net trained on search results has a flatter policy, so sampling from it plays loosely.
What does temperature mean for a policy?
A policy is a list of probabilities over moves. Sampling at temperature 1 picks each move in proportion to its probability, so a flat policy sometimes picks moves it ranks low. Turning the temperature towards 0 makes it pick its top move nearly every time. Training towards search results made this net's policy about twice as flat (entropy from 0.41 to 0.82), yet it still picked the same top move 90% of the time. So the net got no worse. It only looked worse when it was sampled loosely.
I changed the gate to play with search, and the second run promoted four times (generations 2, 4, 5 and 8) before it hit its own kill rule at generation 11. The net from the first run was safe to install in the meantime, because every move in the apps goes through search, so the weakness never shows up in play.
Separately, the exploration noise in that first loop turned out to be degenerate: 24 distinct noise vectors across 112 decisions, when there should have been 112, because the random generator was keyed on the batch index. Two test suites had passed it. A check that can only pass can't catch the failure it's guarding, so every check I add now gets a test that deliberately breaks it.
Some dead ends. I tried giving the net memory with a recurrent layer. To check whether it would help, I tried to identify an opponent's style late in a game: ten hand-made running counters (how many Neighs they've played, whether they passed while holding one, and so on) got it right 67% of the time, a trained recurrent net 31%, and always guessing the most common style 37%. So I dropped recurrence, and adding the counters to the net didn't move its strength either.
A gated league run for three players ended worse than the net it started from: free-for-all 48% down to 29%. The gate used only 50 games, which promoted noise, and training against scripted gang-up opponents seems to have hurt its general play. I kept the original.
I also built a GPU copy of the game to train on. The first version reached about 1,577 random-policy games a second on a rented RTX 3090, but when I checked it card by card, only 23 of the 84 distinct cards behaved exactly like the real engine, and a net fine-tuned on it dropped from about 53% to 23% against the heuristic bot in the real game. I rebuilt it card by card against written specs, until two nets playing each other scored the same on both engines within noise (0.563 against 0.537, each plus or minus 0.056). That made it several times slower per game, and it still can't run tree search, so the AlphaZero runs used the real engine on CPUs.
What is unfinished
Every number above is against scripted bots or earlier versions of the net. I haven't measured it against people, so I don't know how it does against strong ones. What I want next is to put it in front of my friends and family, and to play it myself. One thing the AI's games already showed me is that starting first is a large advantage, much larger than I expected from playing the game by hand. The digital game logs every game it plays, which is where a first human benchmark would come from. The three-player advisor is stateless: you retype the board for each decision. A few rules still differ from the real game. The main one: beginning-of-turn effects resolve one by one in an order the player picks, instead of all at once. The order of other simultaneous triggers is also fixed, and Tiny Stable fires once per entry.
- Stack
- Python, PyTorch, FastAPI, rented cloud boxes for training
- Apps
- Table companion for a physical deck, a digital game with difficulty levels, a three-player advisor, a room mode for two friends
- Status
- Working
- Code
- Not public